

In this article, you will learn how to compare two strategies for adapting a large language model to a specific domain: fine-tuning with LoRA versus training a scikit-learn classifier on frozen embeddings.
Topics we will cover include:
- How frozen embeddings work as a lightweight alternative to full model fine-tuning, and when this approach is appropriate.
- How to implement QLoRA fine-tuning using the PEFT library with a Hugging Face model and a classification head.
- How the two strategies compare in terms of training time and classification accuracy on a real dataset.
Introduction
When adapting an LLM (a large language model) to a specific domain, the classical approach picked by the machine learning community boils down to fine-tuning the model on a domain-specific dataset. But a question arises: is this always necessary? Or could alternative strategies like using frozen embeddings combined with lightweight downstream classifiers on top of the model be a wiser approach to adopt, especially when building cost-friendly, compute-constrained applications?
This article presents a practical comparison of fine-tuning a local LLM with LoRA (Low-Rank Adaptation, an algorithm for efficient weight updating) against training only a downstream scikit-learn classifier on frozen embeddings. We cover, analyze, and discuss when each strategy is preferred based on cost and performance.
To make the most of the practical example below, we recommend a basic level of familiarity with LLMs, key processes like model fine-tuning, and associated libraries like Hugging Face’s transformers.
Initial Setup
If you are running this practical comparison on Google Colab, first and foremost, make sure you set the running environment to GPU (T4), as the code and methods used in it are optimized for GPU use. You will only need to install the following libraries:
|
!pip install –q –U bitsandbytes peft accelerate evaluate |
Otherwise, if you are in a different Python environment, make sure to have scikit-learn, transformers, and datasets also installed before proceeding.
We start by making some of the imports needed and loading a canonical dataset from the Hugging Face repository: ag_news, containing categorized news articles.
|
import torch import numpy as np import time from datasets import load_dataset from transformers import AutoTokenizer, AutoModelForSequenceClassification, BitsAndBytesConfig
# To use Llama-3 instead, change this to “meta-llama/Meta-Llama-3-8B” MODEL_ID = “Qwen/Qwen2.5-1.5B”
print(“1. Loading dataset…”) dataset = load_dataset(“fancyzhx/ag_news”) # A tiny subset is used so that the comparison can be run in minutes, not hours, on GPU train_subset = dataset[“train”].shuffle(seed=42).select(range(800)) test_subset = dataset[“test”].shuffle(seed=42).select(range(200)) |
Next, we load the model instance and its associated tokenizer, ensuring it is configured with a classification head compatible with the specific problem (dataset) at hand, in which news articles are classified into four possible classes:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
print(“2. Configuring Tokenizer…”) tokenizer = AutoTokenizer.from_pretrained(MODEL_ID) tokenizer.pad_token = tokenizer.eos_token # Necessary for decoder-only models
print(“3. Loading Base Model in 4-bit…”) bnb_config = BitsAndBytesConfig( load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_quant_type=“nf4” )
# Loading the model with a classification head model = AutoModelForSequenceClassification.from_pretrained( MODEL_ID, num_labels=4, quantization_config=bnb_config, device_map=“auto” ) model.config.pad_token_id = tokenizer.pad_token_id |
Strategy A: Frozen Embeddings & Scikit-learn
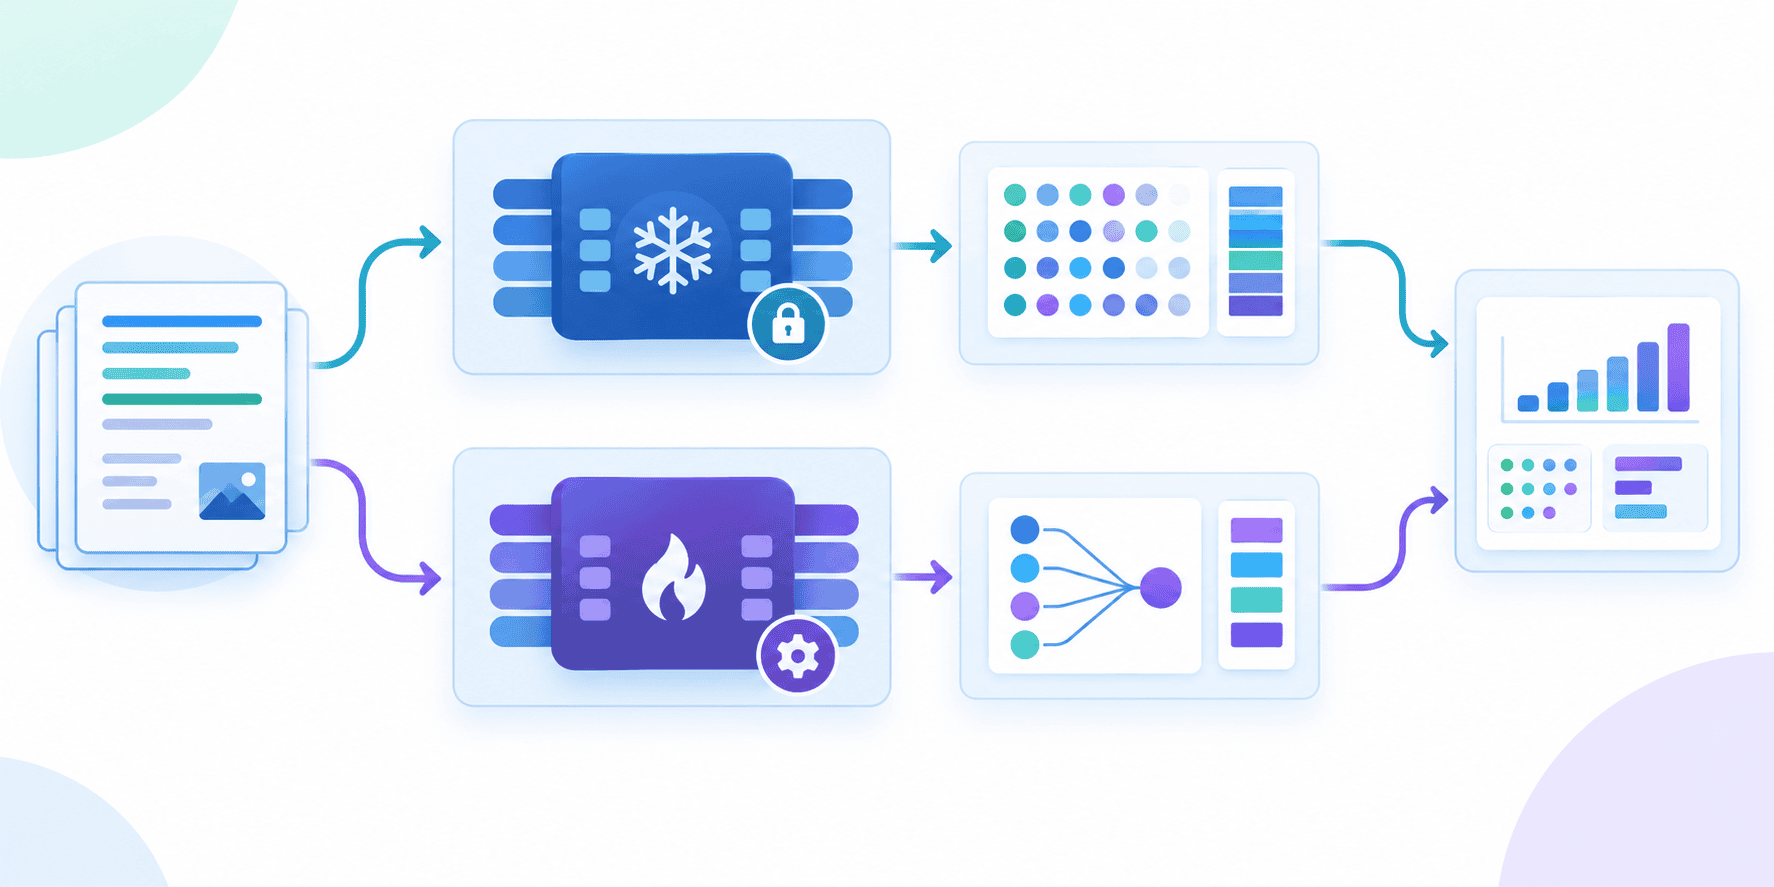
We start by trying out the alternative to fine-tuning our model. It works as follows: instead of retraining the LLM, we make it act strictly as a feature extractor. We pass the text through this “frozen model” (one in which weights cannot change) and extract the last hidden state (the embedding vector) for the final token. These high-dimensional embeddings are then fed to an auxiliary model — in other words, they are used to train a traditional lightweight classifier on top of the frozen LLM.
The first step is defining a function with the internal logic to obtain the frozen embeddings from input texts:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 |
from sklearn.ensemble import RandomForestClassifier from sklearn.metrics import accuracy_score
def extract_embeddings(texts, batch_size=8): model.eval() embeddings = []
for i in range(0, len(texts), batch_size): batch = texts[i:i+batch_size] inputs = tokenizer(batch, return_tensors=“pt”, padding=True, truncation=True, max_length=128).to(model.device)
with torch.no_grad(): # output_hidden_states=True forces the model to return the raw vectors outputs = model(**inputs, output_hidden_states=True) last_hidden_state = outputs.hidden_states[–1]
# Mean pooling: averaging the vectors across the sequence length, ignoring padding tokens mask = inputs[“attention_mask”].unsqueeze(–1).float() sum_embeds = torch.sum(last_hidden_state * mask, dim=1) mean_pooled = sum_embeds / torch.clamp(mask.sum(dim=1), min=1e–9)
embeddings.append(mean_pooled.cpu().numpy().astype(np.float32))
return np.concatenate(embeddings, axis=0) |
Next, we call the function passing our dataset sample — already split into training and test subsets — and obtain the frozen embeddings that will be used to train and test a random forest classifier:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
print(“Extracting embeddings…”) start_time = time.time() X_train = extract_embeddings(train_subset[“text”]) X_test = extract_embeddings(test_subset[“text”]) y_train = train_subset[“label”] y_test = test_subset[“label”] embed_time = time.time() – start_time
print(“Training Scikit-Learn Random Forest…”) clf = RandomForestClassifier(n_estimators=100, random_state=42) start_train_time = time.time() clf.fit(X_train, y_train) sklearn_train_time = time.time() – start_train_time
preds = clf.predict(X_test) sklearn_acc = accuracy_score(y_test, preds)
print(f“\n— Strategy A Results —“) print(f“Extraction Time: {embed_time:.1f}s”) print(f“Classifier Train Time: {sklearn_train_time:.3f}s”) print(f“Accuracy: {sklearn_acc * 100:.1f}%”) |
Results:
|
—– Strategy A Results —– Extraction Time: 96.5s Classifier Train Time: 2.866s Accuracy: 82.0% |
While it took nearly 100 seconds to complete, the vast majority of that time went to the feature extraction process — the classifier training itself was almost instant.
Let’s see whether the 82% test classification accuracy yielded by this frozen embedding-driven classifier can be beaten by a fine-tuned LLM.
Strategy B: LoRA Fine-Tuning (QLoRA)
This strategy uses Low-Rank Adaptation (LoRA): an optimized fine-tuning algorithm that freezes the massive pre-trained weights of the model and injects trainable “adapter” weight matrices into the transformer layers. The complexity of the process boils down to training these small adapter matrices, which typically account for just 1-2% of the total model size, while maintaining 4-bit precision to save memory.
The first two steps are attaching the adapters to the base model and preparing the data for fine-tuning:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 |
from peft import LoraConfig, get_peft_model, prepare_model_for_kbit_training from transformers import TrainingArguments, Trainer import evaluate
print(“1. Attaching LoRA Adapters to Base Model…”) model = prepare_model_for_kbit_training(model) peft_config = LoraConfig( task_type=“SEQ_CLS”, r=16, lora_alpha=32, lora_dropout=0.05, target_modules=[“q_proj”, “v_proj”] # Target attention layers ) lora_model = get_peft_model(model, peft_config) lora_model.print_trainable_parameters()
print(“\n2. Preparing Data for Trainer…”) def tokenize_fn(examples): return tokenizer(examples[“text”], padding=“max_length”, truncation=True, max_length=128)
tokenized_train = train_subset.map(tokenize_fn, batched=True) tokenized_test = test_subset.map(tokenize_fn, batched=True)
accuracy_metric = evaluate.load(“accuracy”) def compute_metrics(eval_pred): predictions, labels = eval_pred predictions = np.argmax(predictions, axis=1) return accuracy_metric.compute(predictions=predictions, references=labels) |
Note that the result of integrating the adapter matrices into our base LLM is stored in a new model variable named lora_model.
We then conduct the core fine-tuning process configured as LoRA — it requires TrainingArguments and Trainer objects:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 |
print(“\n3. Starting QLoRA Fine-Tuning…”) training_args = TrainingArguments( output_dir=“./results”, per_device_train_batch_size=8, per_device_eval_batch_size=8, learning_rate=2e–4, num_train_epochs=3, eval_strategy=“epoch”, logging_strategy=“epoch”, optim=“paged_adamw_8bit”, # Saves VRAM by offloading optimizer states fp16=True, report_to=“none” )
trainer = Trainer( model=lora_model, args=training_args, train_dataset=tokenized_train, eval_dataset=tokenized_test, compute_metrics=compute_metrics, )
start_time = time.time() trainer.train() lora_train_time = time.time() – start_time
print(“\n4. Evaluating QLoRA Model…”) eval_results = trainer.evaluate() lora_acc = eval_results[“eval_accuracy”]
print(f“\n— Strategy B Results —“) print(f“LoRA Train Time: {lora_train_time:.1f}s”) print(f“Accuracy: {lora_acc * 100:.1f}%”) |
Results (you will see more detailed results per training epoch if you execute the code):
|
—– Strategy B Results —– LoRA Train Time: 300.3s Accuracy: 87.0% |
Classification performance does improve when we adapt our model to the specific problem the traditional way: by fine-tuning it. That improvement comes at a cost, however — the entire process took three times as long, with all of that overhead going into the training process itself. For larger datasets, this difference in time may become substantially more pronounced.
Verdict and Conclusion
Feeding frozen embeddings to an auxiliary scikit-learn model is the recommended approach when seeking rapid training and minimal compute overhead while avoiding backbone overfitting. QLoRA fine-tuning, by contrast, is the better choice when closing the accuracy gap is critical to your domain, or when the model needs to learn deeply embedded domain-specific nuances.
This calculus changes for purely generative tasks like text and code generation, where model adaptation — such as fine-tuning — is typically necessary for specialized behaviors. That said, the frozen embedding strategy can sometimes be a viable alternative for generative workflows in free-tier deployments where maximum performance is slightly negotiable.